Work on AI inference.
A short set of guides, a course, and talks on vLLM, llm-d, and running GPUs on Kubernetes.
Community
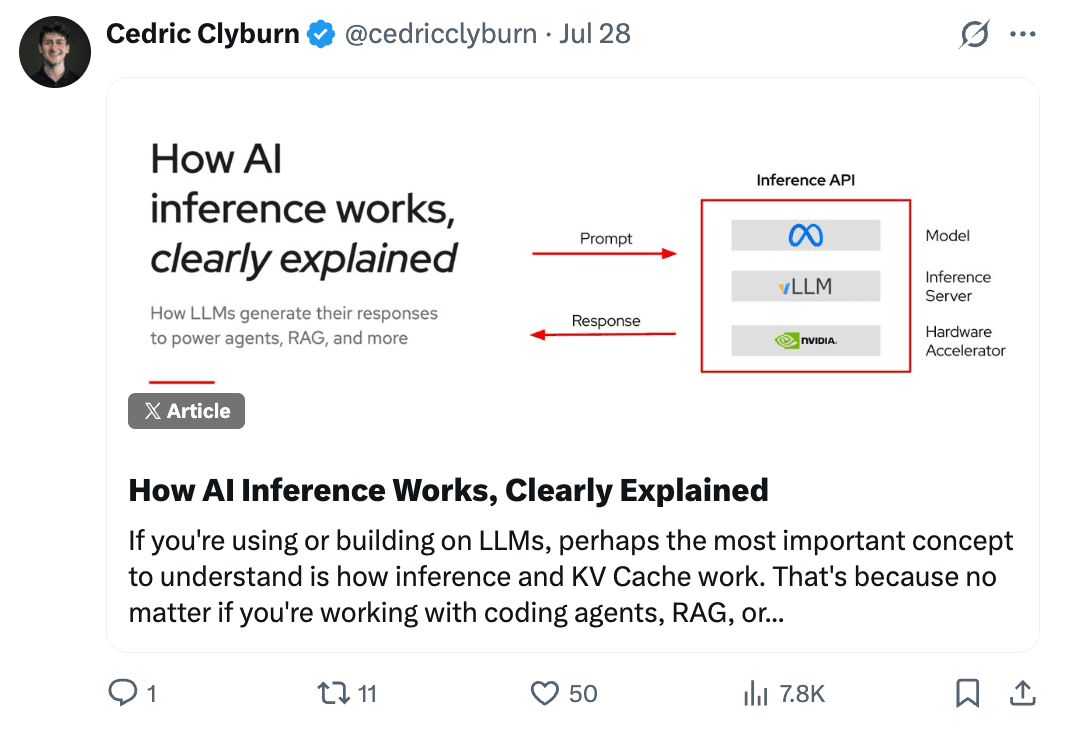
How AI inference works
An Explained article on how inference and the KV cache actually work.
x.com
vLLM vs. SGLang
A benchmarked comparison of the two engines, and when each one fits.
developers.redhat.com
Fast & Efficient LLM Inference with vLLM
Hands-on course: compress a model, serve it with vLLM, then benchmark it.
deeplearning.ai
Customers
GPU-as-a-Service with Kueue and MIG
How a platform team shares NVIDIA GPUs, sliced with MIG and queued with Kueue.
developers.redhat.com
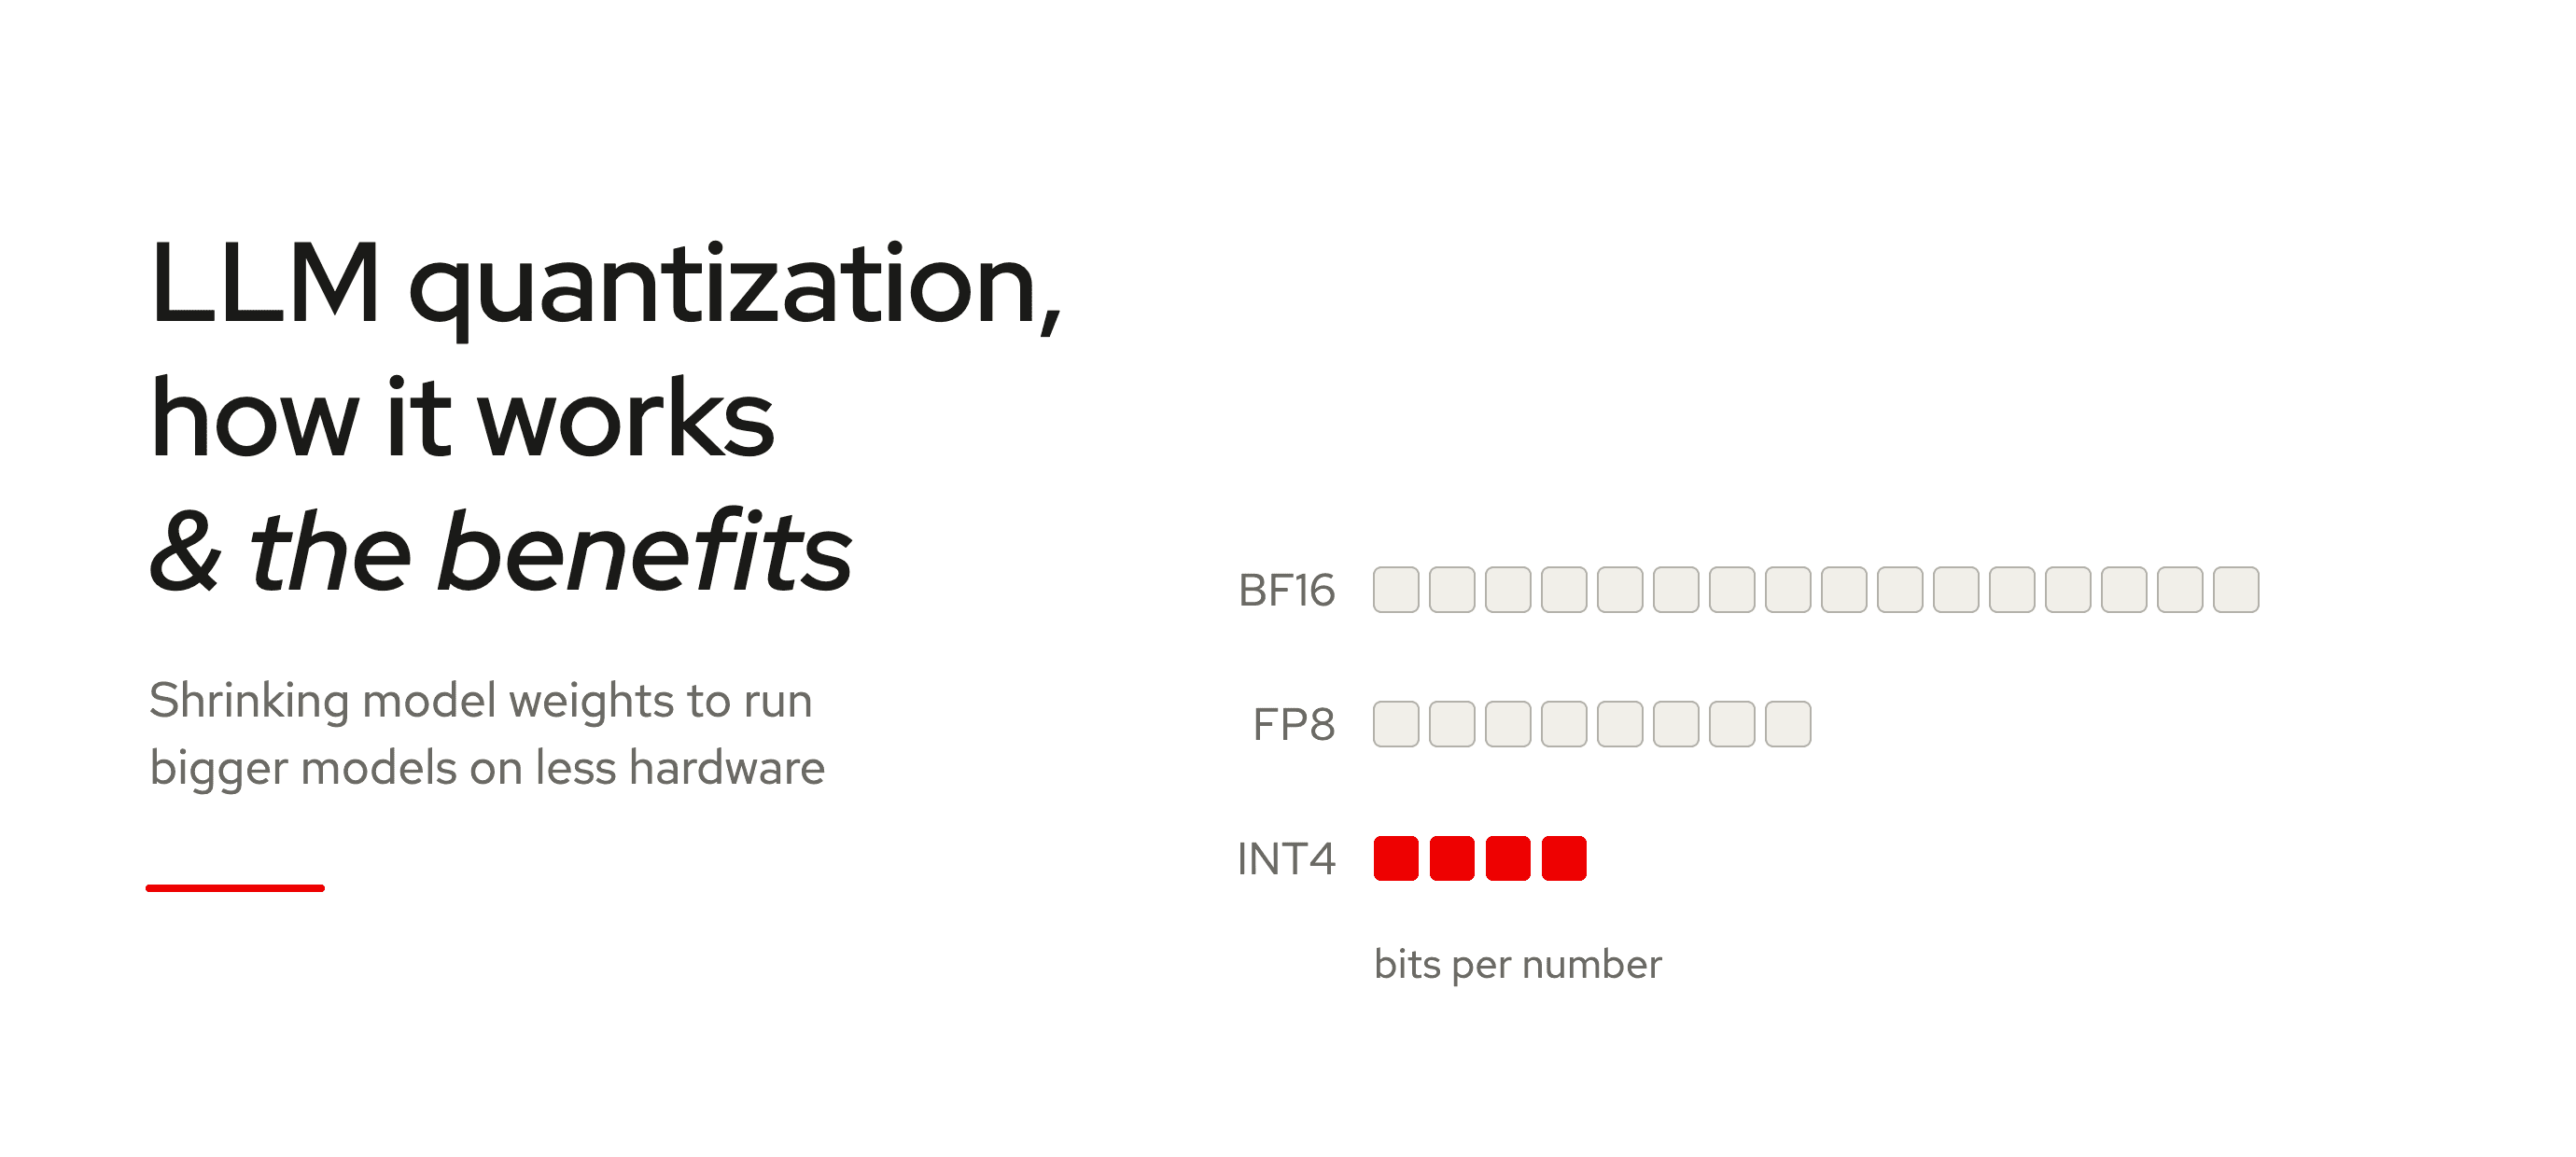
LLM quantization guide
What quantization changes, and what it does to GPU count and cost.
developers.redhat.com
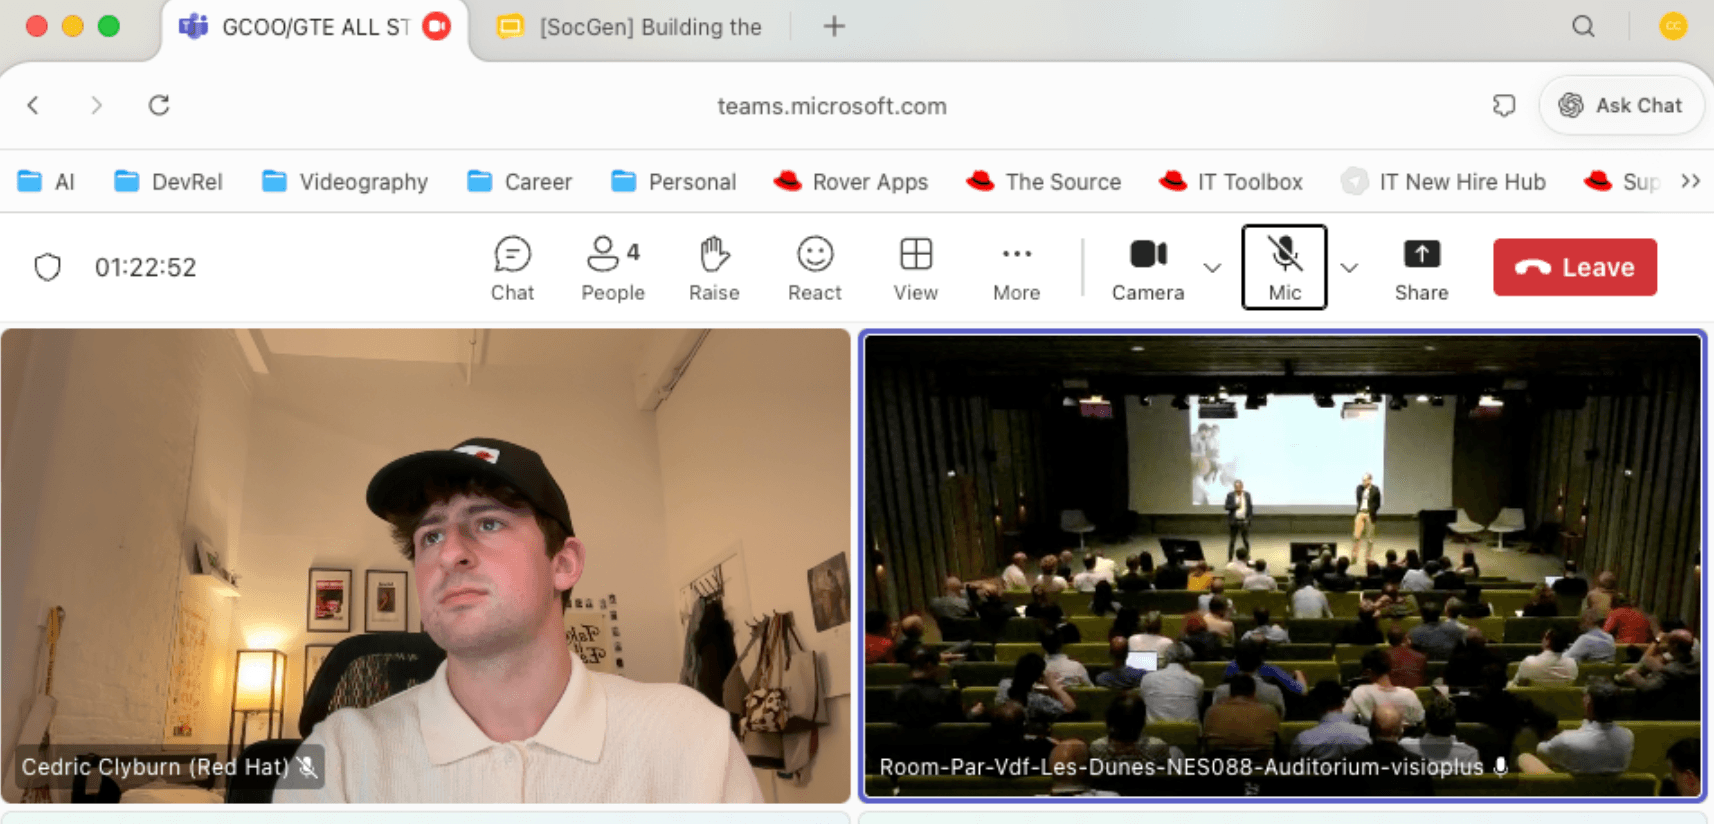
Société Générale town hall
A CTO-style session at Société Générale’s Les Dunes auditorium.
Developer engagement
Essential skills for an AI engineer
A whiteboard on the skills behind RAG, agents, and inference.
youtube.com
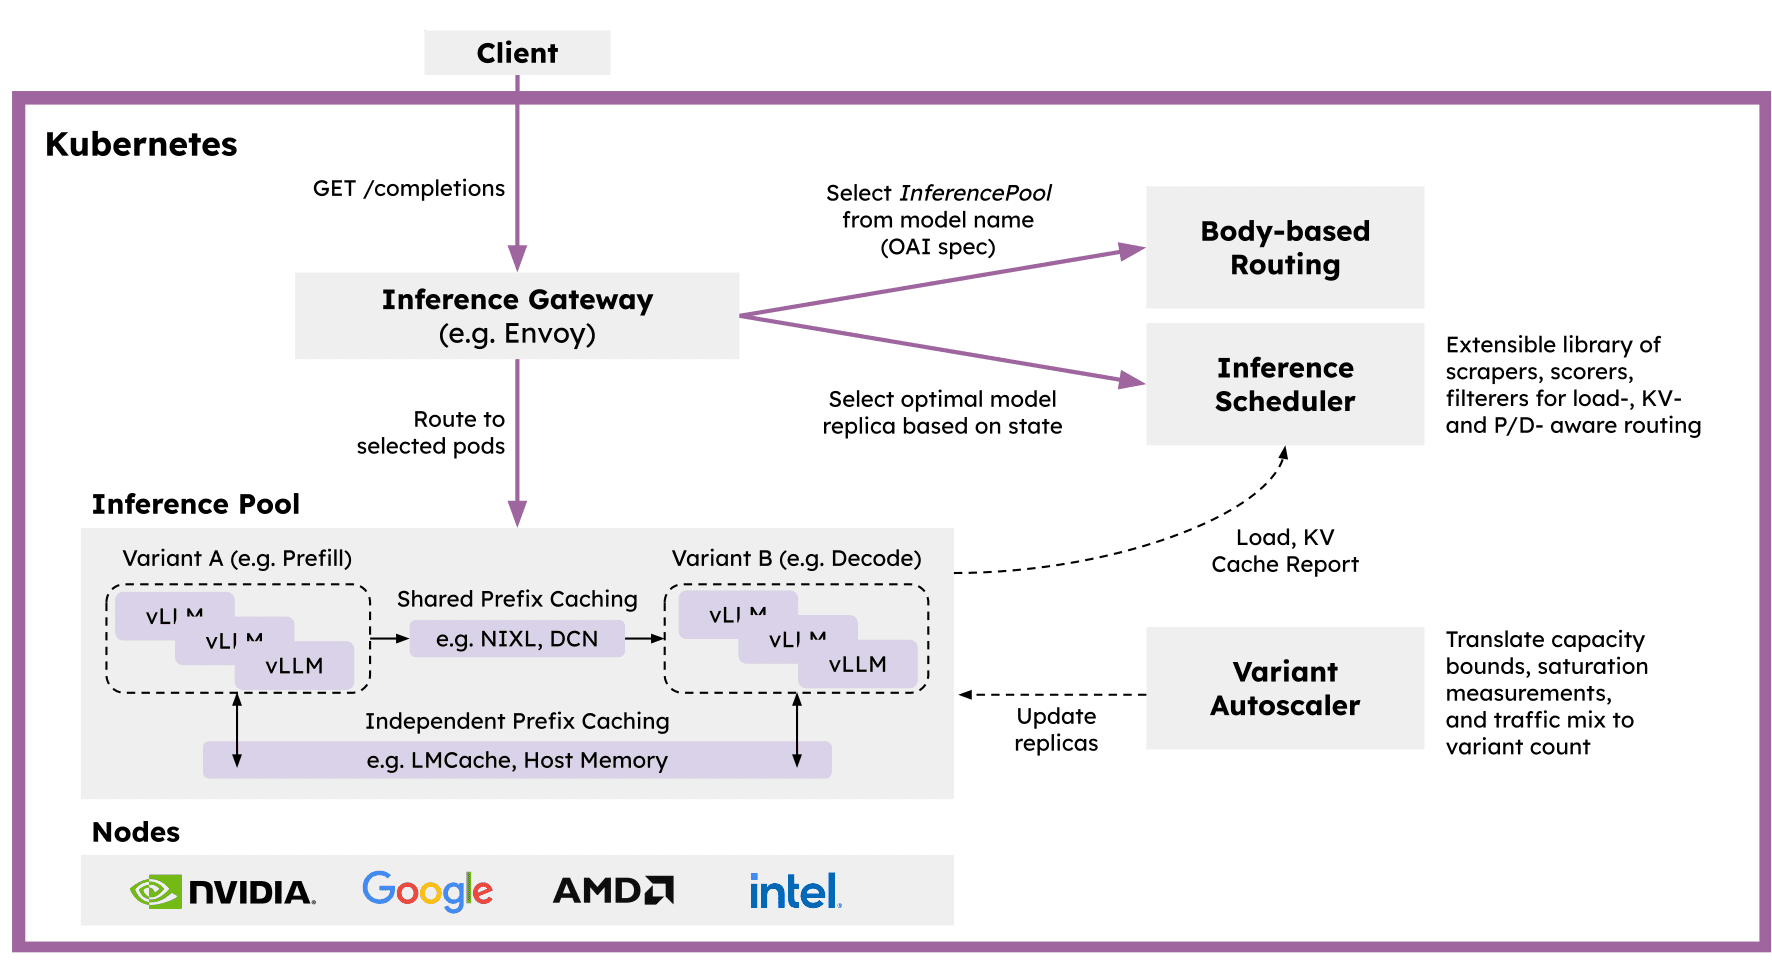
Getting started with llm-d
A hands-on look at llm-d routing on KV cache and splitting prefill from decode.
developers.redhat.com
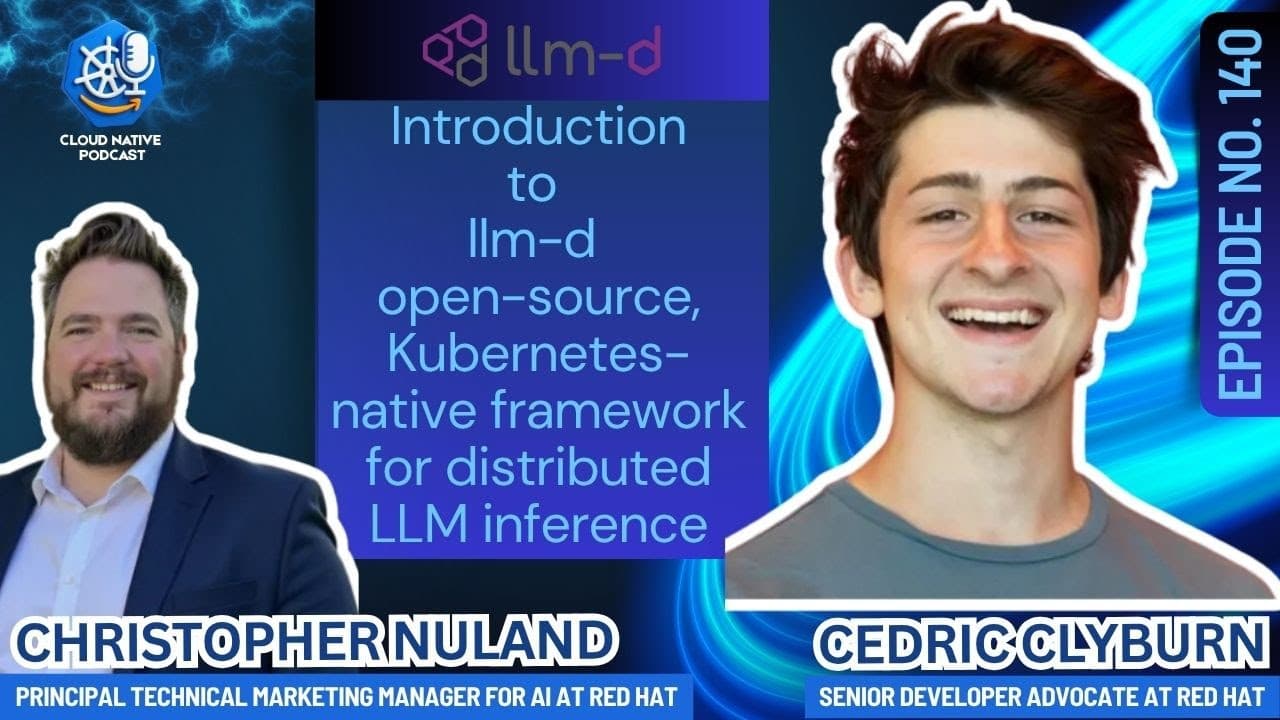
Introduction to llm-d
A podcast on why a normal Kubernetes load balancer mishandles LLM traffic.
youtube.com